Stale Retrieval in RAG-Augmented Agent Workflows
Trace which harness layer let outdated context slip through to your model.
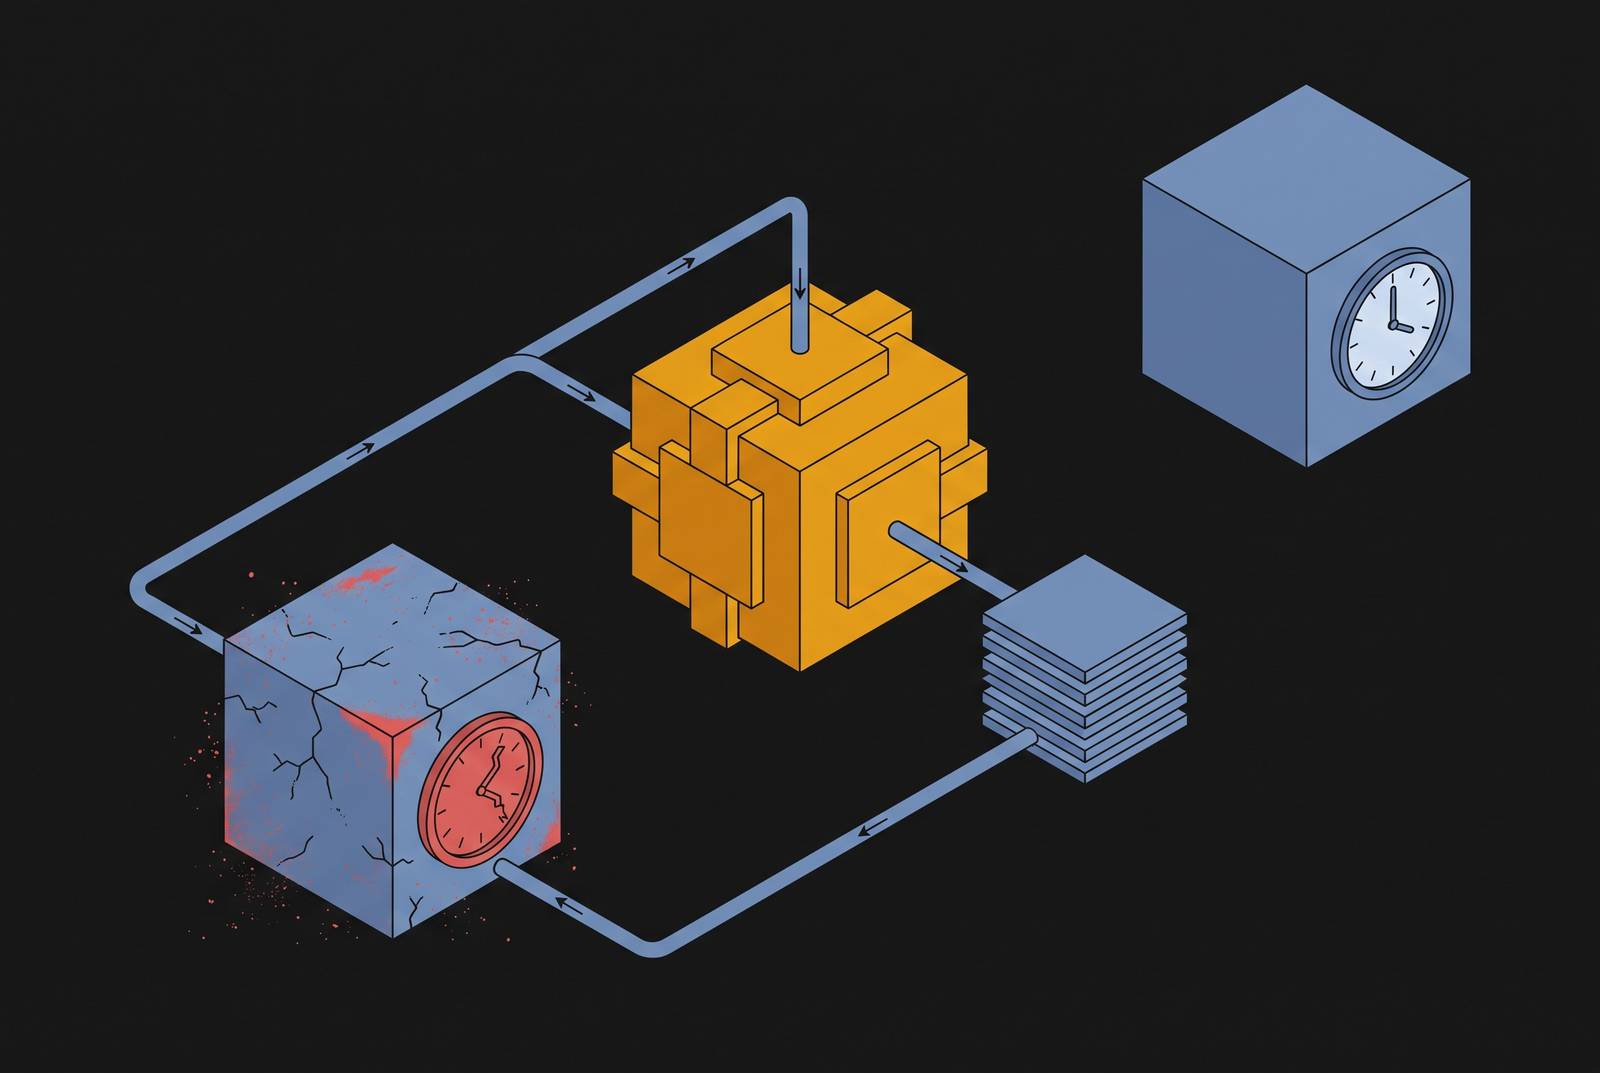
Stale retrieval in RAG-augmented agent workflows is a harness engineering problem. Outdated context gets to the model because the index pipeline, retrieval logic, or validation layer lets it through. The effective fix begins by tracing where that happened, then changing and testing the responsible layer rather than tuning the model that exposed the failure.
Why stale retrieval is a harness failure, not a model limitation
A deployed agent returns old pricing, a deprecated API path, or a superseded policy confidently and without flagging uncertainty. The answer looks like a model failure because the generated answer contains the error. Yet the model received outdated material as its evidence, with nothing in the workflow challenging its validity.
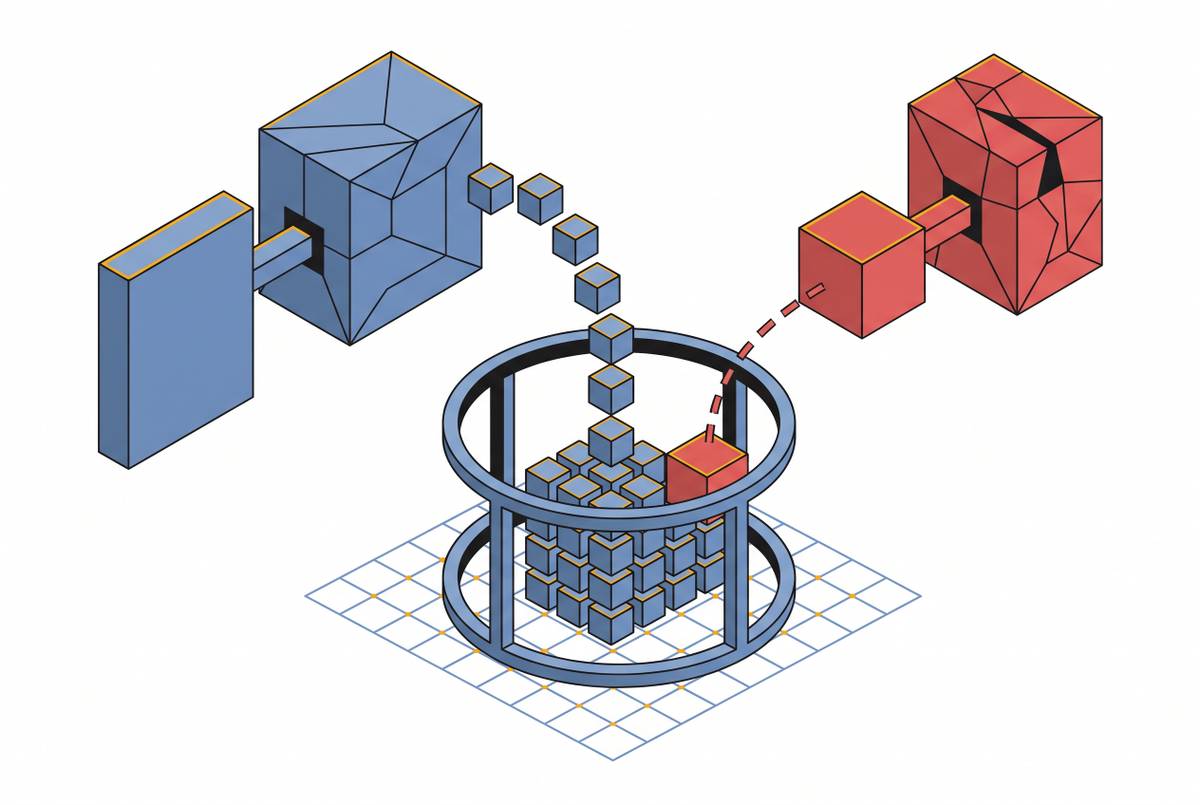
That distinction puts responsibility on the harness, which controls what gets indexed, how documents are selected, and whether retrieved context is checked. Semantic similarity measures relevance to a query independently of document recency, so a strong retrieval score provides no assurance that the evidence remains valid. Without a freshness gate, outdated material can pass through without an error signal. Swapping the LLM, increasing context length, or adjusting temperature leaves those conditions intact.
How the retrieval harness is structured and where staleness enters it
The pipeline begins with source ingestion and indexing. Documents in the vector store carry embeddings computed at indexing time, but those embeddings do not establish when the document was valid or whether another version has superseded it. This makes the index the earliest entry point for stale context. An old API document can still be semantically relevant after the API changes, and an obsolete document that is longer than its replacement may have more semantic surface area.
Retrieval then selects chunks for the query, and a reranker may change their order before they enter the context supplied to generation. These are separate opportunities to distinguish relevance from freshness. A timestamp stored with a document is useful only if the selection or ranking logic uses it. Otherwise, the pipeline can carry freshness metadata without letting that metadata affect its decisions.
In an agentic workflow, another layer controls when and how this sequence runs. Singh et al.'s agentic RAG survey describes agents that dynamically manage retrieval strategies and adapt workflows. The agent decides whether to retrieve, which retriever to call, how often to loop, and when to stop. Generation is the final opportunity to catch stale evidence, but a judge that checks a draft only against the retrieved chunks can approve an answer that faithfully repeats outdated facts.
The three harness design choices that make staleness systematic rather than occasional
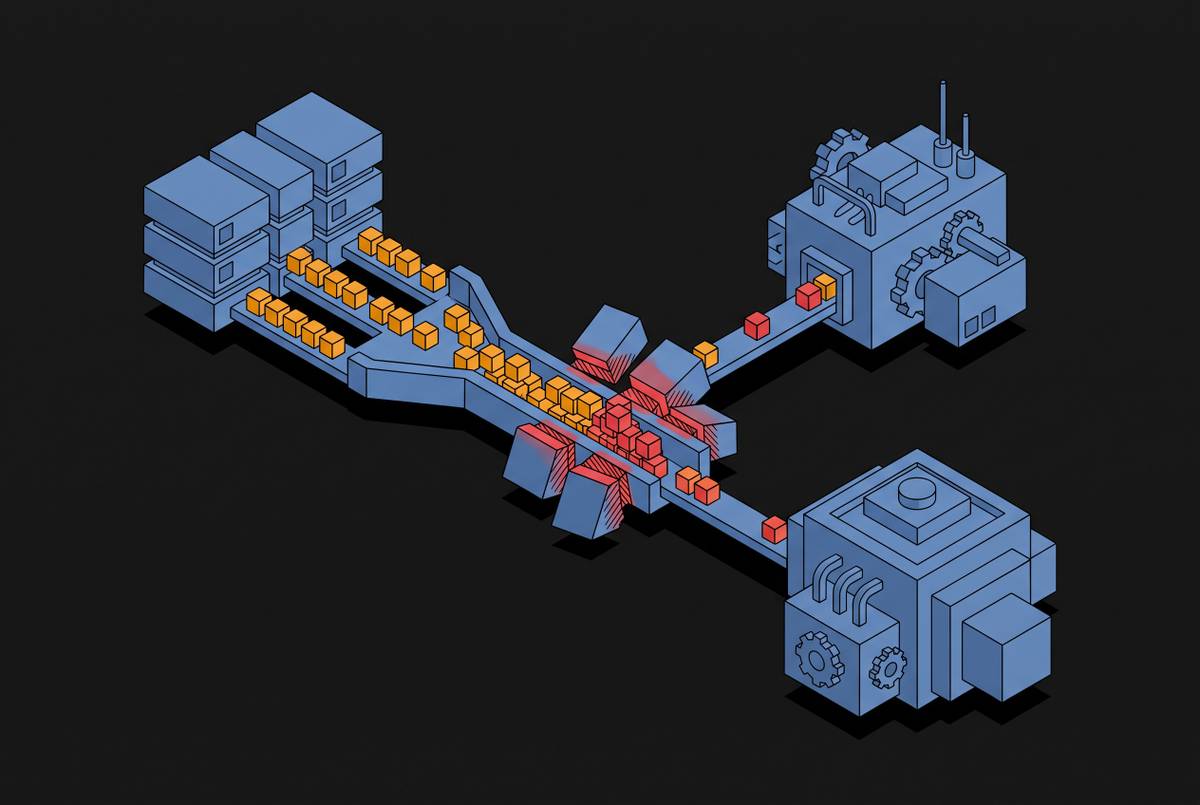
The first choice is batch re-indexing on a schedule. Processing the corpus periodically can simplify processing and control cost while delaying updates. For frequently changing pricing, product documentation, or policy documents, however, nightly re-indexing leaves the index stale for much of the day. The lag is not a random retrieval error but a consequence of the chosen update schedule. A change at the source can affect retrieval only after the pipeline processes it.
The second choice is similarity-only scoring. Semantic closeness provides a direct way to find relevant passages, but it does not distinguish a current fact from an obsolete statement about the same subject. When conflicting versions coexist, the retriever has no basis for preferring the newer one unless freshness enters the score. The LLM may then fabricate a resolution to the conflict without flagging uncertainty.
The third choice is passing retrieved chunks to the model without a validation gate. Omitting a freshness check, version check, or judge reduces pipeline complexity, but it also removes the opportunity to reject outdated evidence before generation. In an agentic workflow, repeated retrieval can accumulate those chunks across hops before any final output is scored.
Why agentic workflows make stale retrieval harder to detect and costlier to ignore
The agent layer does not fix flaws in the retrieval harness on its own. Instead, it can carry stale context from one reasoning hop into the query used for the next. Singh et al.'s agentic RAG survey describes reflection, planning, tool use, and multi-agent collaboration as ways to refine contextual understanding iteratively. Those capabilities need evidence the agent can trust as it reasons. If an early premise is outdated, later reasoning can build on the undetected error.
Repeated retrieval creates a second form of amplification. Without a hard step budget or a clear stop signal, an agent can retrieve the same stale document again and take that result as proof that it was right. The extra retrieval has added no independent evidence, yet it can reinforce the original premise. The resulting answer may be structurally coherent because the agent reasoned carefully from the context it received. That coherence makes the failure harder to distinguish from a sound answer than an obvious confabulation would be.
The consequences can also extend beyond the current turn. Ding et al.'s always-on agents survey treats retrieved memories as part of an agent's durable state, which shapes how it acts later. Stale retrieval can therefore affect not only the immediate reasoning chain but also the state available to later interactions. The agent's added persistence and autonomy make the existing harness failure more consequential.
Tracing which harness layer let the stale context through
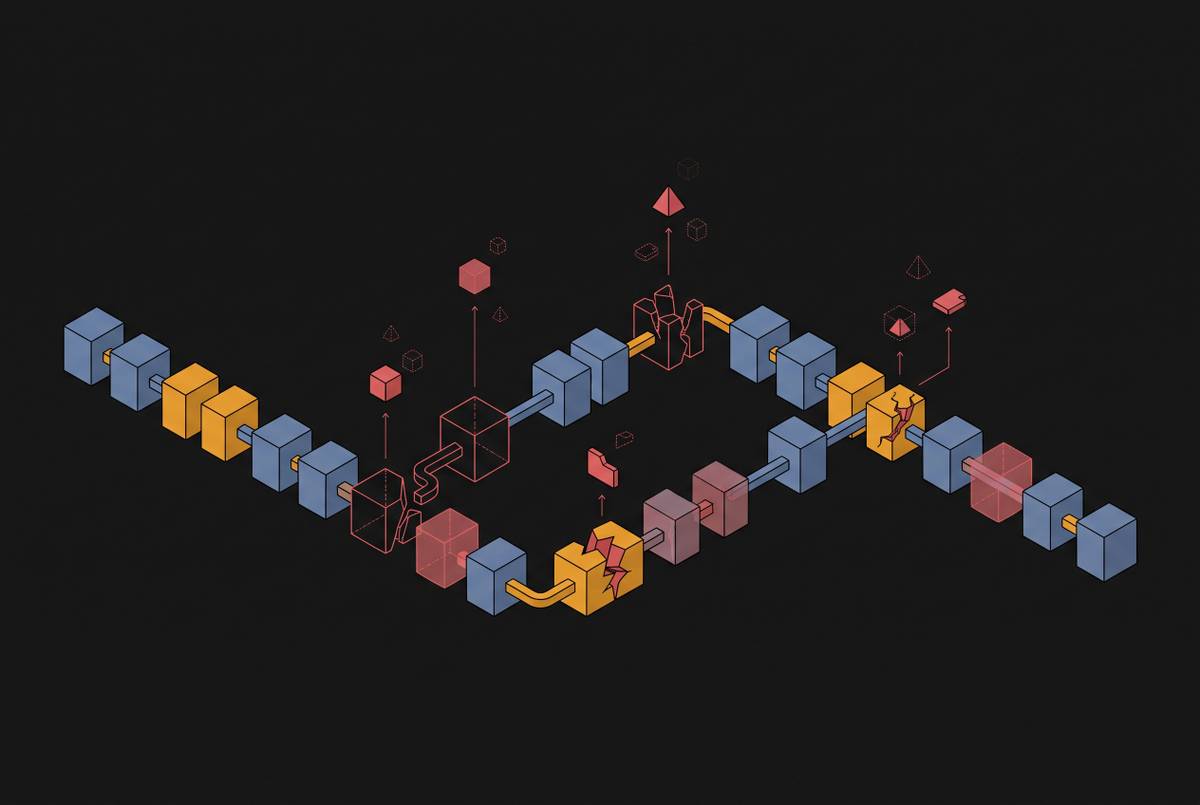
Diagnosis requires span-level tracing because an incorrect final answer does not identify where the evidence became unreliable. Each stage should emit a structured span with enough metadata to establish whether stale content entered there and whether the stage had the information to reject it. The investigation follows the evidence through the index, retrieval, reranker, and generation layers. Its central distinction is between a missing freshness signal and an available signal that went unused.
At the index layer, check the document version, ingestion timestamp, and source last-modified date. These fields help show whether material was already outdated at ingestion or became stale before query time. If the document was obsolete when ingested, the source ingestion logic or index update schedule is the relevant failure layer. If it was current at ingestion, the investigation must account for what changed before retrieval. An ingestion timestamp alone does not establish that a document was valid when returned.
At retrieval, check the similarity score, chunk ID, and how old the document was at query time. These fields show what was selected and whether recency information was available to influence selection. A document returned without recency weighting despite carrying a timestamp points to retrieval logic leaving available metadata unused. The reranker span then establishes whether a freshness-weighted score was applied or whether the second ranking stage used semantic relevance alone. Separating these spans prevents a reranking omission from disappearing inside a broad diagnosis of retrieval quality.
At generation, establish whether a faithfulness or grounding judge ran and what it evaluated. Consistency with retrieved chunks is not the same as temporal validity, so a passing judgment can coexist with stale evidence. If indexing and retrieval look correct but no gate checks for outdated material before generation, the missing evaluation layer is a flaw in the architecture. Attribution should identify both where a freshness signal went unused and where stale content passed onward without a gate. That distinction matters because an index update cannot repair scoring logic, and recency weighting alone cannot resolve conflicting documents left in the index.
The fixes that belong to each harness layer once attribution is established
An attributed index pipeline failure calls for a change to ingestion. Moving from batch re-indexing to event-driven ingestion lets source changes trigger re-embedding without waiting for a full-corpus run. Change Data Capture (CDC) from the source database can drive that pipeline so only changed documents generate new embeddings. This ties index freshness to source changes rather than a cron schedule. This cuts update lag, but retrieval still needs a freshness rule if one is missing.
A retrieval logic failure calls for freshness to enter the scoring function. A timestamp-weighted reranking step can penalize documents beyond a defined validity window, while a hybrid score can combine semantic similarity with recency. Agent tool routing should also pick out time-sensitive queries, including questions about pricing, policy, and versioned API. Those queries can use a retriever with recency weighting or a live-fetch tool that bypasses the index. A team with event-driven ingestion but similarity-only retrieval needs this scoring correction.
An architectural failure calls for a validation gate between retrieval and generation. Before the draft is written, the judge must check both factual grounding and temporal validity, going beyond a check that the answer agrees with the supplied context. In an agentic workflow, a hard step budget should bound retrieval iterations so a failed freshness check can trigger another attempt without creating an endless loop. The gate should also appear as a scored, inspectable span that records which retrievals were rejected and why. Teams can choose among these fixes to match the failures they traced, without having to use all of them in order.
Validating harness changes against production traces before shipping them
A new reranking weight, freshness gate, or step budget can fix the cases it was designed for while regressing on others. Validation should therefore begin with the production traces where stale retrieval occurred. Those traces keep the actual queries and document distribution behind the failure, which a synthetic benchmark may not capture. The test should target the span that failed as well as evaluate the aggregate answer score.
Apply the harness change to the failing traces and check whether retrieval now returns fresh documents, whether the gate catches material it missed before, and whether the final answer is correct. These are distinct checks because a change at one stage does not by itself establish success downstream. Previously passing traces must also be evaluated for regressions. If the change improves the failing cases but harms others, the trace store makes that tradeoff visible before deployment.
Reviewability is a required part of this validation. Engineers need to inspect which documents were re-ranked, which chunks triggered the freshness gate, and which traces passed or failed after the change. Without an audit trail, a confidence score cannot show whether the improvement came from the change as intended. The evidence for shipping should therefore connect the changed harness behavior to both the repaired failures and any regressions.
What treating staleness as a harness engineering problem changes about the workflow
The reframe changes ownership from an undirected complaint about the model to bounded engineering responsibilities. The index pipeline owner is responsible for index freshness, the retrieval logic owner for recency weighting, and the evaluation layer owner for the validation gate. It also changes what constitutes a fix. A better-looking answer is not enough without evidence that the responsible layer now handles the stale context differently.
Monitoring follows the same shift from outputs to causes. Final-answer quality is a lagging signal, while document age distributions, freshness gate rejection rates, and re-retrieval trigger rates show what is changing inside the harness. Retrieval mechanics alone are insufficient because stale source data limits the accuracy that ranking improvements can achieve. Recurrence in the same document domain is therefore diagnostic evidence. It can point to a source missing from the CDC pipeline, a document type without an update trigger, or a validity window too wide for the domain's change rate.
The durable practice is to attribute the failure, repair the responsible layer, replay the relevant traces, and monitor the spans that reveal recurrence. This makes stale retrieval a repeatable engineering investigation rather than another round of model tuning. It is the same rigor a mature team applies to code review and testing, extended to the retrieval harness.